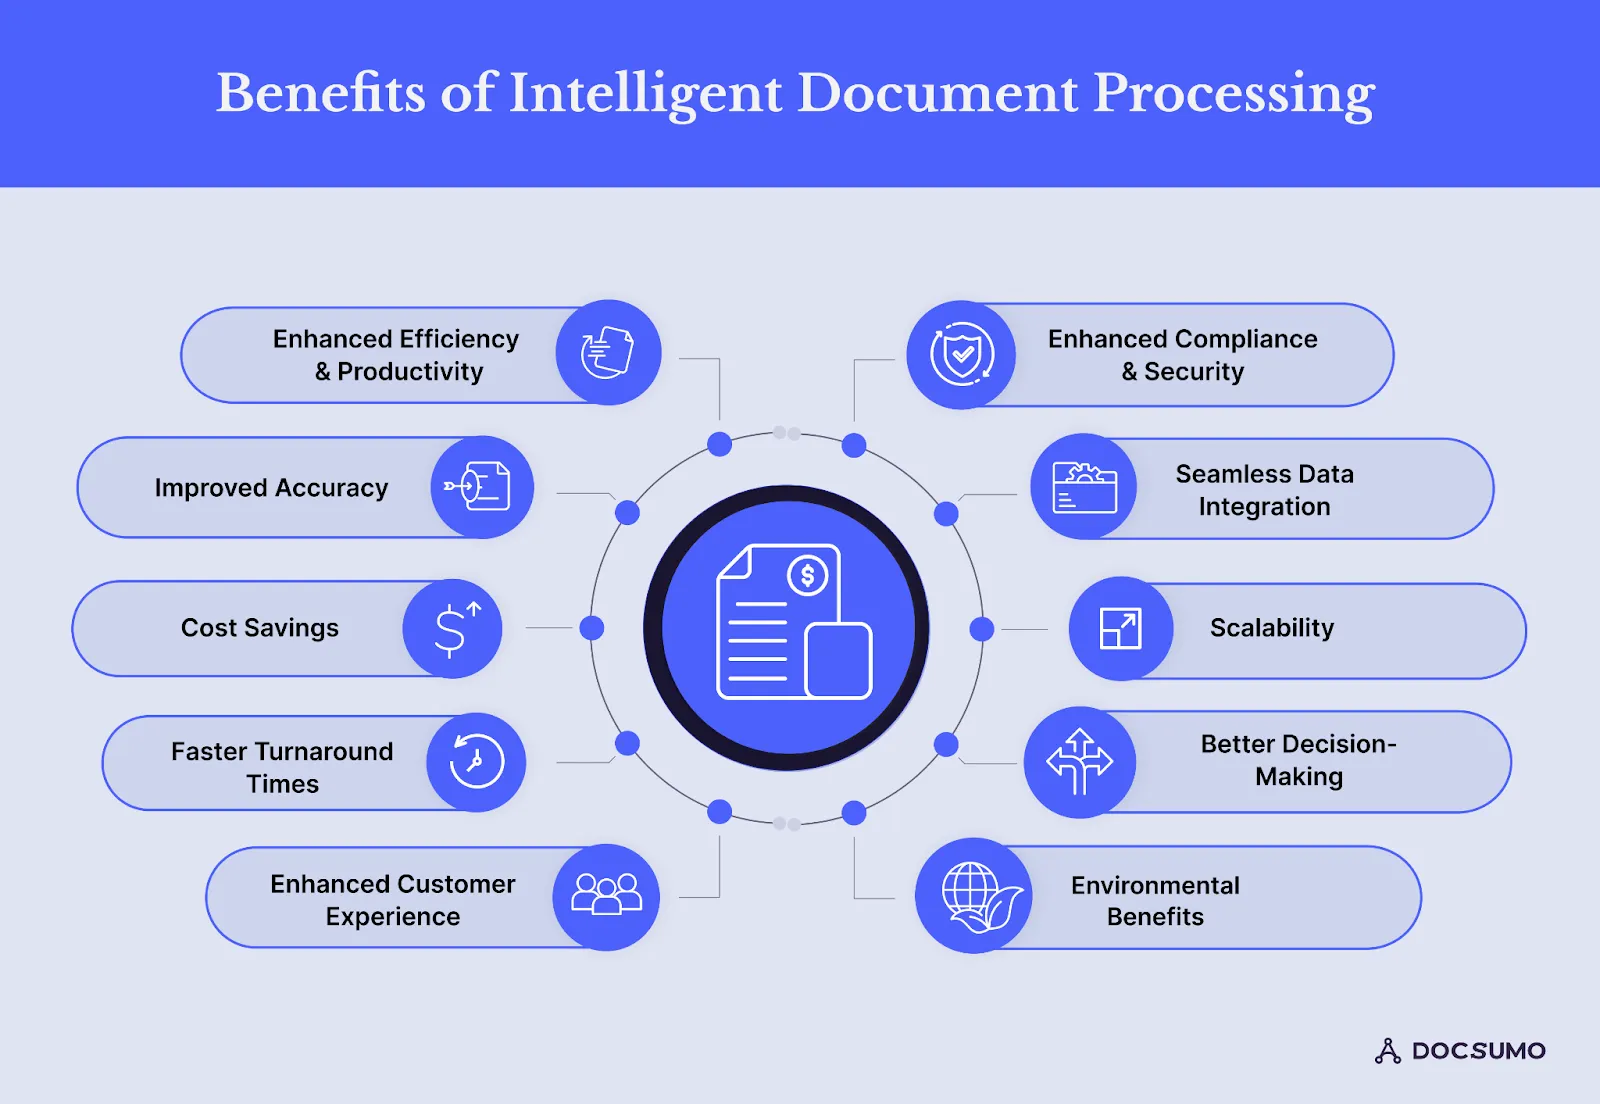
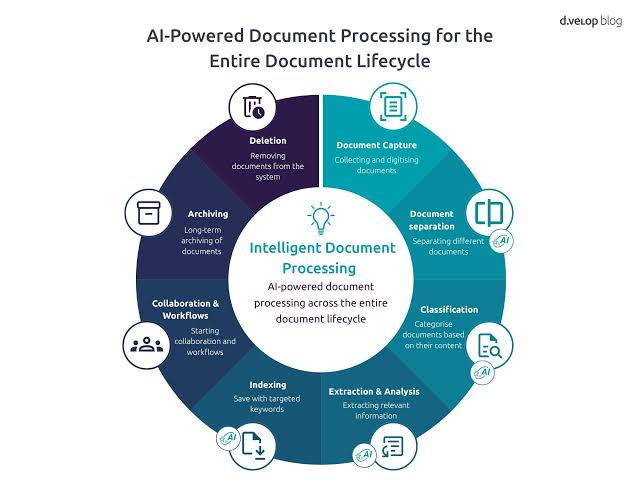
Someone on your team is still keying invoice totals, contract terms, or form fields into a system by hand. It's slow, it's error-prone, and it doesn't scale past a certain volume no matter how careful they are.
We build extraction pipelines that read unstructured documents and turn them into structured data your systems can use — with validation on anything the model isn't confident about, so bad data doesn't slip through unnoticed.
Whether it's invoices, contracts, applications, or claims forms, we architect the pipeline around your document formats and downstream systems.
What We Build Into Your Pipeline
1. OCR Plus LLM Extraction: OCR reads the raw text and layout, and an LLM interprets it in context — catching fields that pure OCR alone misreads or misplaces.
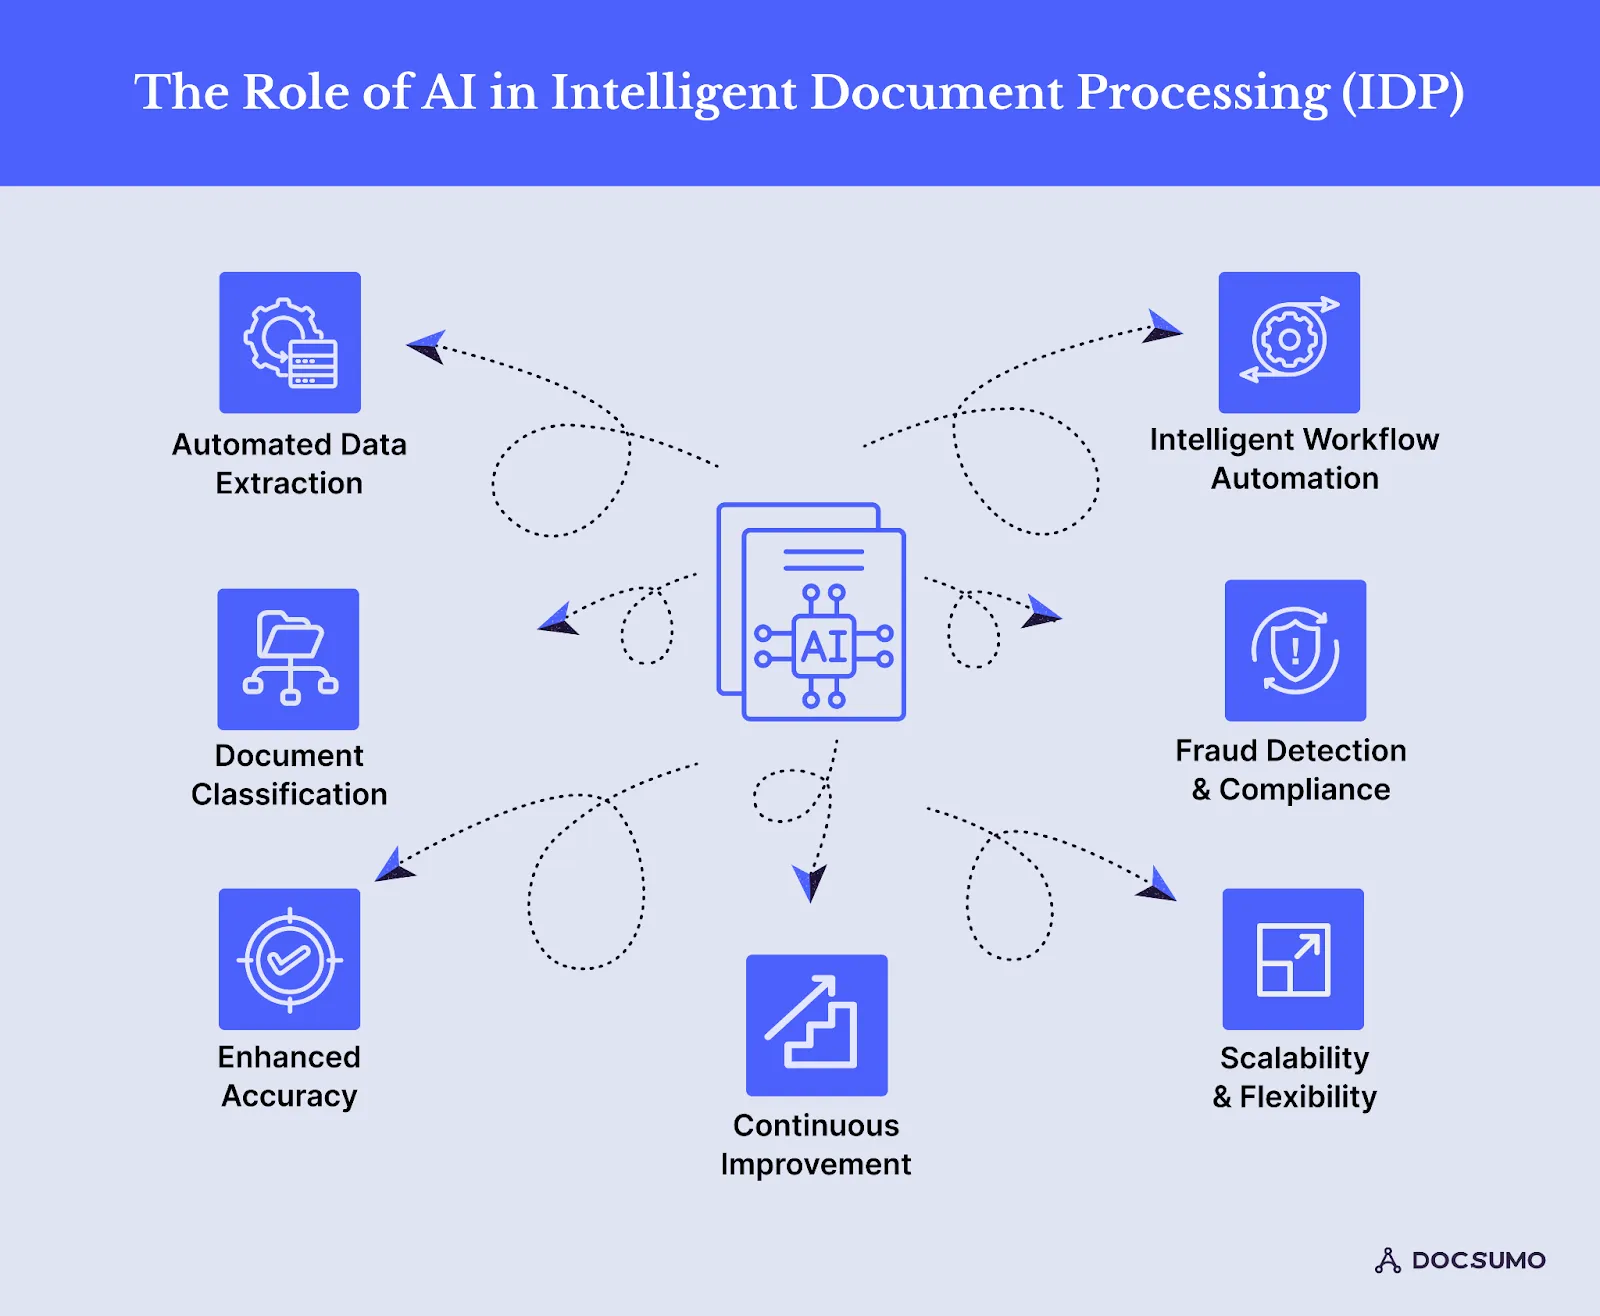
2. Structured Output From Messy Formats: Handwritten notes, scanned faxes, and inconsistent layouts across vendors all get normalized into the same structured fields.
3. Confidence Scoring on Every Field: Each extracted value gets a confidence score, so the system knows what it's sure of and what needs a second look.
4. Exception Handling That Catches Problems: Low-confidence extractions get routed for human review instead of flowing straight into your ERP or CRM as if they were verified.
5. Integration Into Systems You Already Use: Extracted data lands directly in your ERP, CRM, or accounting system, so someone isn't re-keying what the pipeline already extracted.
Why Choose Akantik for Document Intelligence?
An extraction pipeline that's silently wrong is worse than one that's obviously broken — bad data flows downstream and nobody notices until it causes a real problem. We build the review layer in from day one.
Built Around Your Actual Document Set: We train and tune extraction against your real documents and vendor formats, not a generic sample set that doesn't reflect what you actually receive.
Exceptions Are a Feature, Not a Failure: We design the review workflow so low-confidence cases get caught and fixed fast, instead of becoming a bottleneck.
Accuracy Improves Over Time: We monitor extraction accuracy after launch and refine the pipeline as new document types and edge cases show up.
Still keying data from documents into your systems by hand? Let's find out how much of it can be automated.
Common questions about AI-powered document extraction and processing.
Document intelligence is the use of OCR and AI to extract structured data from unstructured documents like invoices, contracts, and forms, turning scanned or PDF documents into usable data for your business systems.
Common document types include:
Every extracted field gets a confidence score.
Low-confidence extractions are flagged and routed to a human reviewer instead of being automatically accepted, so uncertain data doesn't silently flow into downstream systems.
Yes, we build integrations so extracted data lands directly in your existing ERP, CRM, or accounting system, eliminating manual re-entry of data the pipeline has already extracted and validated.
Accuracy depends on document quality and consistency, but well-tuned pipelines typically achieve high accuracy on structured fields.
Confidence scoring and human review of low-confidence cases keep overall data quality high even when individual extractions are uncertain.