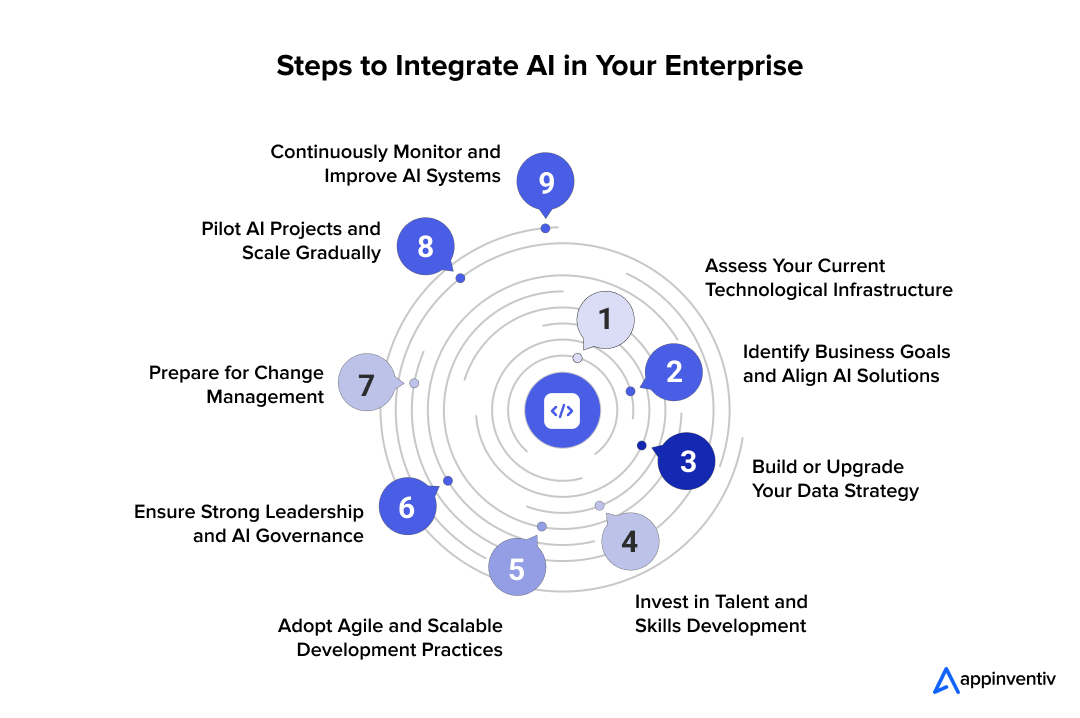
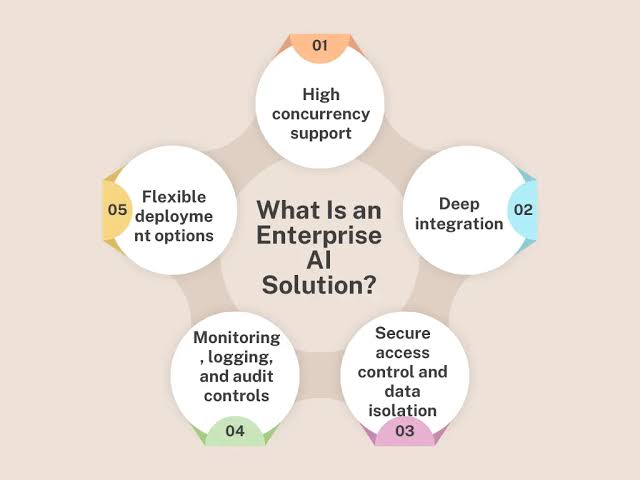
A model that works in a notebook and a model that works in production are two different problems. We take a validated use case — from strategy or a proof of concept — and build it out as a system your business can actually depend on.
That means deployment pipelines, integration with the systems your team already uses, and monitoring that catches drift before it becomes a customer-facing problem.
Whether you're scaling a successful PoC or implementing a use case that's already well understood, we build for the maintenance burden your team will actually carry after we hand it off.
What Implementation Includes
1. MLOps and Deployment Pipelines: Models are versioned, tested, and deployed through a repeatable pipeline — not pushed to production by hand whenever someone remembers to.
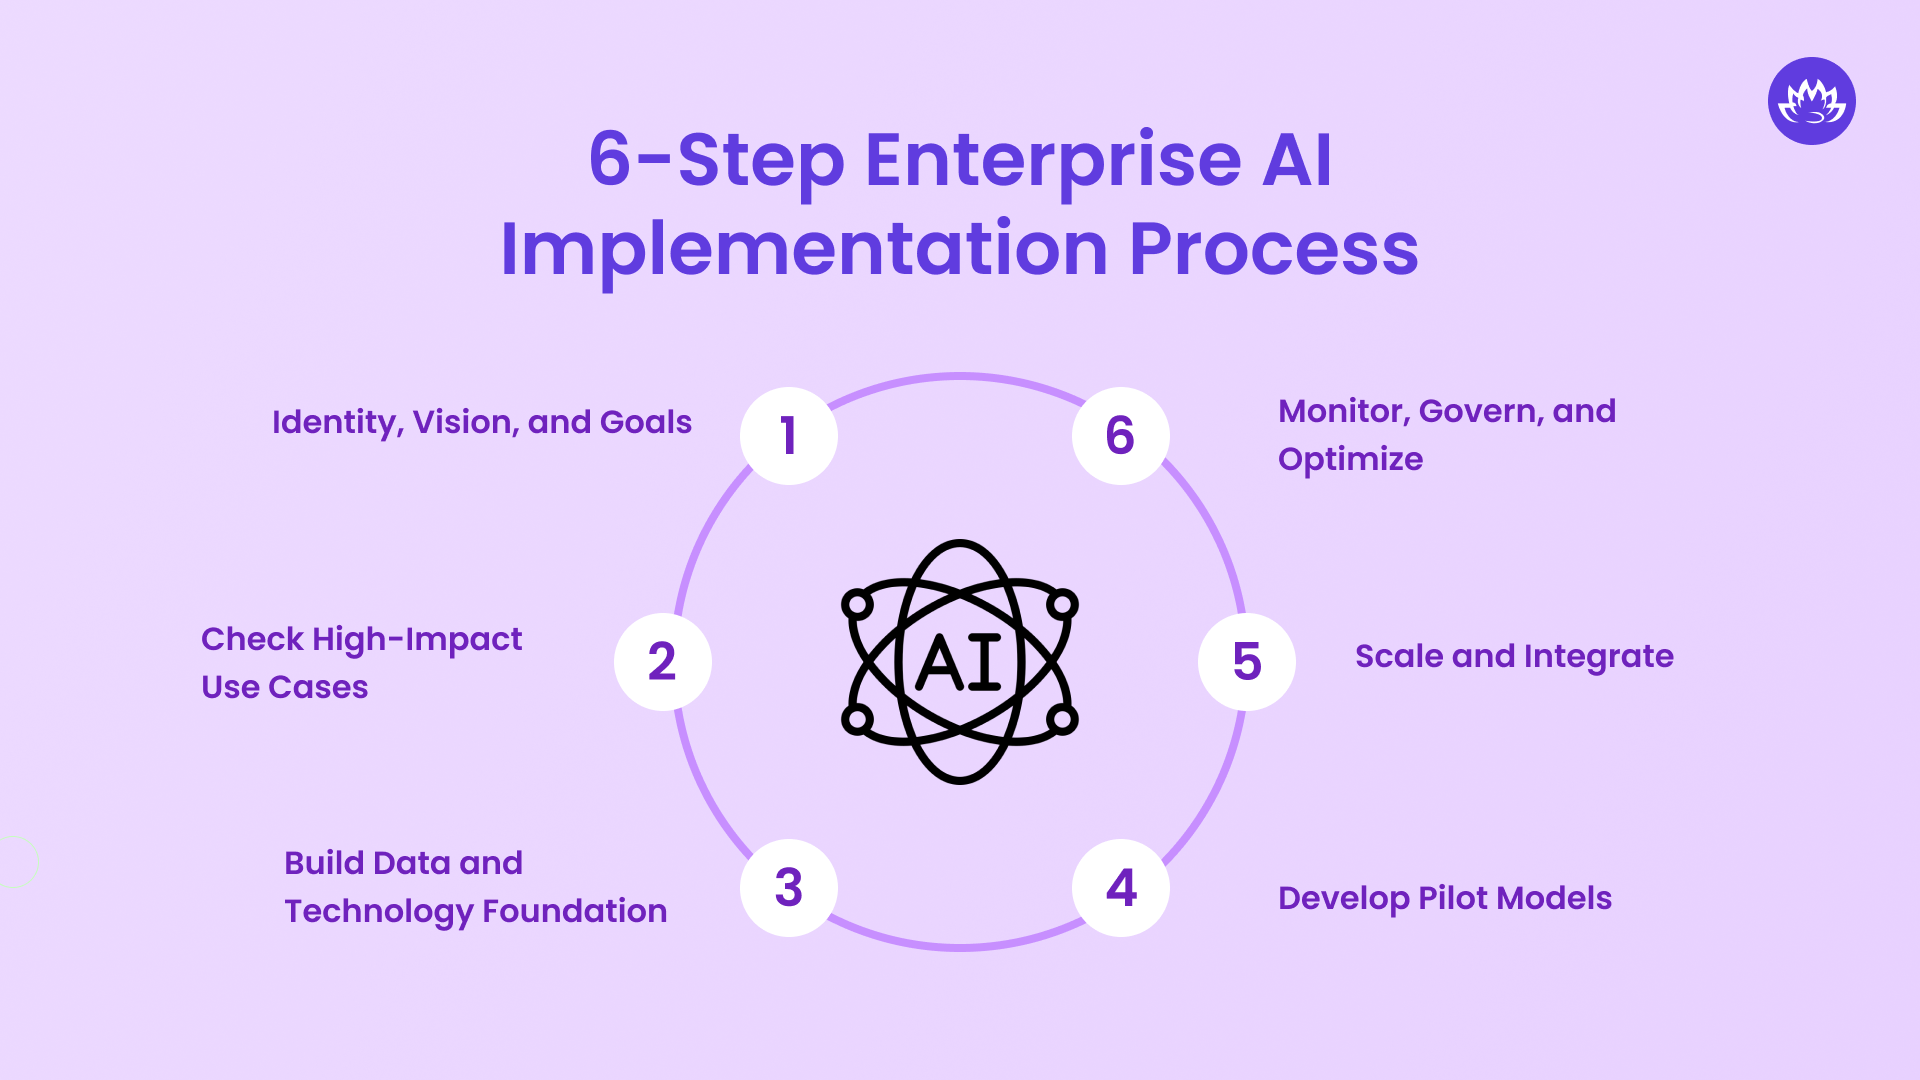
2. Integration With Production Systems: The model gets wired into your CRM, ERP, data pipelines, or customer-facing app — so it's part of a workflow people actually use, not a standalone tool that gets forgotten.
3. Change Management and Adoption: We work with the teams who'll use the system day-to-day, so rollout doesn't stall because nobody trusts or understands the output.
4. Monitoring and Drift Detection: Model performance is tracked after launch, so degradation from changing data patterns gets caught early, not discovered months later in a customer complaint.
5. Retraining and Ongoing Tuning: We set up the process to retrain and refine the model as real usage data accumulates, so accuracy doesn't quietly decay after go-live.
Why Choose Akantik for AI Implementation?
A model deployed without monitoring is a model quietly getting worse. We build implementations meant to be run for years, not demoed once.
Production Engineering, Not Just Data Science: Our team builds the deployment pipelines, integrations, and monitoring alongside the model itself — so it's a system, not a script someone has to babysit.
Handoff That Doesn't Leave You Stuck: We document the system and train your team to operate it, so it doesn't become a black box the day we step back.
Support That Continues After Go-Live: We stay involved through monitoring and retraining cycles, since an AI system's job isn't done at launch.
Have a validated AI use case that needs to become a real production system? Let's build it.
Common questions about deploying AI systems to production.
Implementation includes MLOps pipelines for deployment, integration with production systems, change management for user adoption, and ongoing monitoring and retraining — everything needed to run the model reliably, not just build it once.
Not always. If the use case is well understood and low-risk, we can move straight to implementation. For novel or high-uncertainty use cases, a proof of concept first reduces the risk of a full build that doesn't pan out.
Model drift is when a model's accuracy degrades over time because real-world data patterns shift away from what it was trained on. We set up monitoring to detect drift and retraining pipelines to correct for it.
Yes, we integrate AI implementations with existing enterprise systems including ERP, CRM, and internal APIs, so the model's output feeds directly into workflows your team already uses.
Yes, we offer ongoing monitoring, performance tuning, and retraining support after launch, so the system stays accurate as real usage data accumulates.